Building and Deploying Interactive Research Applications and APIs in R (IRAR01)
Learn to build and deploy interactive research applications and APIs in R using Shiny, Plumber and Quarto. Practical online training for researchers.
 Duration: 5 Days, 5 hours per day
 Next Date: March 1-5, 2027
 Format: Live Online Format
UK (GMT+0) local time - All sessions will be recorded and made available to ensure accessibility for attendees across different time zones.
£400Registration Fee
Register NowLike what you see? Click and share!


- Overview
- Instructors
- Schedule
Course Description
Reproducible analysis is an essential foundation, but it does not by itself make research outputs easy to find, understand, or use. This five-day course explores how to move beyond reproducibility by choosing and building appropriate ways to share research results: reports and downloadable data products, static and dynamic APIs, and interactive applications.
Participants will consider the needs of their intended audiences and learn when a static resource, an API, or a user interface is the most useful delivery pattern. Using JSON, Plumber, Shiny, and Shinylive, the course connects research outputs to practical, user-facing tools and decision-support applications. Hands-on exercises will reinforce these concepts and provide practical experience in building and deploying interactive research applications using various free tools and platforms and virtual environments provided by the course instructors.
The final part of the course covers the operational work that makes these outputs sustainable: hosting options, versioning and update workflows, availability and usage monitoring, and security and access control. Through examples and hands-on exercises, participants will leave with a practical framework for turning reproducible research into reliable, accessible resources that others can use.
What You’ll Learn
- Transform reproducible research outputs into accessible, interactive applications and data services.
- Identify when to use static resources, APIs or interactive applications to share research findings.
- Understand the fundamentals of web technologies, including HTTP, URLs, JSON and RESTful APIs.
- Create and publish static research outputs, including reports, datasets and spatial data using R Markdown and Quarto.
- Build dynamic APIs in R using Plumber to provide programmatic access to research data and analyses.
- Design and develop interactive web applications and dashboards using R Shiny.
- Use Shinylive to create interactive R applications that run directly in a web browser.
- Deploy research applications and APIs using GitHub Pages, Posit Connect, shinyapps.io and cloud hosting platforms.
- Integrate databases and external data sources into research applications and APIs.
- Implement authentication, access controls and security measures to protect research applications and data.
- Manage application updates, versioning, performance and availability monitoring.
- Apply continuous integration and deployment (CI/CD) principles to maintain reliable, sustainable research applications.
Course Format
Interactive Learning Format
Each day features a well-balanced combination of lectures and hands-on practical exercises, with dedicated time for discussing participants’ own data, time permitting.
Global Accessibility
All live sessions are recorded and made available on the same day, ensuring accessibility for participants across different time zones.
Collaborative Discussions
Open discussion sessions provide an opportunity for participants to explore specific research questions and engage with instructors and peers.
Comprehensive Course Materials
All code, datasets, and presentation slides used during the course will be shared with participants by the instructor.
Personalized Data Engagement
Participants are encouraged to bring their own data for discussion and practical application during the course.
Post-Course Support
Participants will receive continued support via email for 30 days following the course, along with on-demand access to session recordings for the same period.
Who Should Attend / Intended Audiences
Researchers, graduate students, and research-support staff who want to make their data, analyses, and findings more accessible and useful beyond a report or manuscript.
Analysts, data scientists, and technical teams in academic, public, private, and non-profit sectors who need practical guidance for delivering research outputs as websites, downloadable resources, APIs, or interactive applications.
R users from fields such as ecology, environmental science, public health,and related disciplines who want to build and operate user-facing tools for research or decision support.
Equipment and Software requirements
A laptop or desktop computer with a functioning installation of R and RStudio is required. Both R and RStudio are free, open-source programs compatible with Windows, macOS, and Linux systems.
A working webcam is recommended to support interactive elements of the course. We encourage participants to keep their cameras on during live Zoom sessions to foster a more engaging and collaborative environment.
While not essential, using a large monitor—or ideally a dual-monitor setup—can significantly enhance your learning experience by allowing you to view course materials and work in R simultaneously.
All necessary R packages will be introduced and installed during the workshop. A comprehensive list of required packages will also be shared with participants ahead of the course to allow for optional pre-installation.

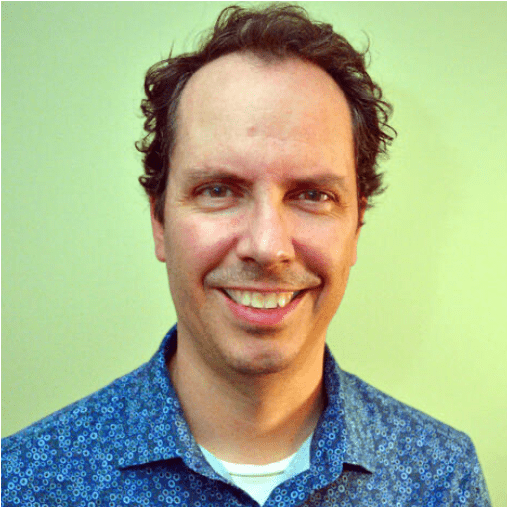
Dr. Péter Solymos
Péter is an ecologist and scientific programmer whose work integrates large-scale ecological data analysis with advanced statistical modelling in R. His research focuses on developing flexible, reproducible tools for estimating species population densities and understanding ecological patterns across continental-scale datasets. Péter’s methodological contributions are widely recognized, particularly in handling complex and “messy” ecological data arising from imperfect surveys.
He is the author and maintainer of several well-known R packages used across ecological and statistical communities, including detect, dclone, vegan, and ResourceSelection, which support everything from hierarchical modelling to data cloning and resource use analysis. Beyond academic research, Péter applies his statistical expertise in industry, currently working as a data scientist helping utility companies improve outage prediction and impact mitigation strategies.
Péter also holds an adjunct faculty position at the University of Alberta in Edmonton, Canada, where he contributes to ecological research and mentorship in statistical computing and environmental modelling.
Education & Career
• Adjunct Professor, University of Alberta
• Data Scientist, Applied Predictive Analytics in the Energy Sector
• Author and maintainer of open-source R packages for ecological analysis
Research Focus
Péter’s work centers on scalable methods for ecological inference, particularly in the context of abundance estimation, imperfect detection, and model-based survey analysis. He is passionate about open science, reproducibility, and building tools that bridge ecological theory with practical data challenges.
Current Projects
• Developing R tools for estimating species density from imperfect survey data
• Applying predictive analytics to improve outage prevention in utility services
• Contributing to statistical and ecological workflows for large-scale biodiversity monitoring
Software & Tools
• detect – Tools for estimating detection probabilities and abundance
• dclone – Data cloning methods for Bayesian model calibration
• vegan – A foundational package for community ecology analysis
• ResourceSelection – Tools for analyzing habitat and resource use
Teaching & Skills
• Expert in R programming, hierarchical modelling, and Bayesian inference
• Active mentor in ecological statistics and open-source software development
• Promotes reproducible and efficient data analysis workflows across sectors
Links
• Google Scholar
• Work Homepage
• Personal Homepage
Why reproducibility is just the beginning
- Reproducible work can still be hard for others to discover, access, or apply.
- The goal is not just to share results, but to make them usable.
- Ways to share scientific results
- Reports, manuscripts, and supplementary materials.
- Data products and downloadable files.
- Interactive tools and decision-support applications.
- Delivery patterns for research outputs
- Static file APIs
- Dynamic APIs
- User interfaces
- The World Wide Web
- URL structure and components (scheme, host, path, query)
- HTTP basics (requests, responses, status codes)
- Testing access to virtual servers and software tools used in the course
Introduction to APIs and endpoints
- Differences between static and dynamic APIs
- Use cases and examples, when to use static file APIs
- The JSON API specification
- Hosting and serving static files
- Versioning and documentation
- Performance considerations (CDNs, caching)
- Security considerations (access control, HTTPS)
- Spatial data considerations (GeoJSON, GeoTIFF, map tiles)
- Static Rmarkdown and Quarto documents (html, PDF; reports, books)
- Hosting static files
- Choosing a hosting provider
- Configuring the server for static content
- Handling updates and versioning
- CORS (Cross-Origin Resource Sharing) configuration
- Hands-on exercises for hosting static files
- Generating various types of static files (HTML, JSON, GeoJSON, GeoTIFF)
- Using GitHub Pages for hosting static files
- Using AWS S3 and Amplify Hosting for static files
- Using virtual servers for hosting static files (Caddy Server, Let’s Encrypt)
Dynamic APIs
- RESTful APIs
- CRUD operations (Create, Read, Update, Delete: how they map to HTTP methods)
- Versioning and documentation
- Error handling and response codes
- Advanced topics
- Authentication and authorization
- Rate limiting and throttling
- Pagination and filtering
- Caching and performance optimization
- Webhooks and event-driven APIs
- API gateways and microservices architecture
- SQL databases and queries, Postgres and REST APIs
- Hands-on exercises for hosting dynamic APIs
- Writing and deploying a simple dynamic API using R and Plumber
- Using virtual servers for hosting dynamic APIs (Caddy Server, Let’s Encrypt)
User interfaces
- When a user interface is more useful than raw files or an API
- Shiny
- Shinylive
- Interactive Rmarkdown and Quarto documents
- Review of hosting options
- Hands-on exercises for user interfaces:
- Hosting platforms, such as Posit Connect, Shinyapps.io
- Static file hosting options for Shinylive
- Embedding Shiny apps in websites using iframes
User interfaces
- Shiny continued
- Hands-on exercises for user interfaces:
- Self-hosted solutions: Shiny Server (Caddy Server, Let’s Encrypt)
- Security and access control
- Versioning and update workflows
- Monitoring availability and usage
- Continuous integration and continuous deployment (CI/CD)
- Advanced deployment strategies (containerization, orchestration)
Testimonials
PR Stats offers a great lineup of courses on statistical and analytical methods that are super relevant for ecologists and biologists. My lab and I have taken several of their courses—like Bayesian mixing models, time series analysis, and machine/deep learning—and we've found them very informative and directly useful for our work. I often recommend PR Stats to my students and colleagues as a great way to brush up on or learn new R-based statistical skills.
Rolando O. Santos
PhD Assistant Professor, Florida International University

Courses attended
SIMM05, IMDL03, ITSA02, GEEE01 and MOVE07
Testimonials
PR Stats provided excellent training in stable isotope analysis through the SIMMPR course, which was incredibly valuable for my research. I was fortunate to attend the course through a generous fee waiver, which directly supported my work and enabled me to develop skills that contributed to my recent publication on reservoir food webs in Sri Lanka. I’m very grateful for the opportunity and support, and would highly recommend their courses to others working in ecological research.
Subodha Silva
Aquatic Ecology Researcher
Courses attended
SIMMPR
Testimonials
PR Stats has become an invaluable part of developing my skills in advanced statistical and spatial analysis. Through training in areas such as Bayesian statistics and Species Distribution Modelling, I’ve gained both practical expertise and exposure to leading experts in the field. The impact on my research has been significant with at least four of my published papers have been directly influenced by PR Stats courses. My most recent work benefitted from modelling advice on sample design and model accuracy evaluation and can be seen here.
Carlos P.E. Bedson
Quantitative Spatial Ecology, Ecology and Environment Research Centre, Manchester Metropolitan University, United Kingdom
Courses attended
ADVR08, ENMR03, BMIN02, ISBD01, BADA01, SDMB06
Frequently asked questions
Everything you need to know about the product and billing.
When will I receive instructions on how to join?
You’ll receive an email on the Friday before the course begins, with full instructions on how to join via Zoom. Please ensure you have Zoom installed in advance.
Do I need administrator rights on my computer?
I’m attending the course live — will I also get access to the session recordings?
I can’t attend every live session — can I join some sessions live and catch up on others later?
I’m in a different time zone and plan to follow the course via recordings. When will these be available?
I can’t attend live — how can I ask questions?
Will I receive a certificate?
When will I receive instructions on how to join?
You’ll receive an email on the Friday before the course begins, with full instructions on how to join via Zoom. Please ensure you have Zoom installed in advance.
Do I need administrator rights on my computer?
I’m attending the course live — will I also get access to the session recordings?
I can’t attend every live session — can I join some sessions live and catch up on others later?
I’m in a different time zone and plan to follow the course via recordings. When will these be available?
I can’t attend live — how can I ask questions?
Will I receive a certificate?
Still have questions?
Can’t find the answer you’re looking for? Please chat to our friendly team.